Insatiable speed demands of
AI inference

Purpose-built for agentic inference

The SambaNova RDU chip delivers faster tokens, more models per rack, and dramatically better energy efficiency — working in your data center side-by-side with your existing infrastructure. Our platform is purpose-built to power large-scale AI inference for organizations running production AI.

How does SambaNova do it?

Our unique architecture creates an assembly line of operations that eliminates the memory bottlenecks. Memory and compute run in parallel on-chip, keeping activations local and drastically reducing the power demanded for data movement.

  • Dataflow Architecture - Model bundling runs multiple models efficiently on the same system
  • Three-Tier Memory - Optimized memory hierarchy designed specifically for AI workloads
  • Energy-Efficient Inference - Higher performance per watt compared to traditional GPU infrastructures

The result is infrastructure that allows service providers to deliver more AI capability with fewer systems and less power.

Connect with a SambaNova Expert

DevTalks: Designing Effective AI Agents

Join SambaNova and CrewAI for an in-depth webinar on Designing Effective AI Agents — exploring how developers, enterprise AI teams, and entrepreneurs can build, orchestrate, and deploy agentic systems that deliver real results.

In this live session, Justin Woo (SambaNova) and Shane K. Johnson (CrewAI) will demonstrate how to combine CrewAI’s powerful orchestration framework with SambaCloud’s blazing-fast inference to create agents that are both intelligent and efficient.

Date: November 18th

Time: 10am PT | 1pm ET 

What You’ll Learn:

  • What AI agents are and why they matter

  • How CrewAI enables multi-agent orchestration and workflow automation

  • How SambaCloud powers scalable, high-performance inference for agents

  • Core principles of effective agent design 

  • Best practices for building and deploying real-world agentic systems

No liquid cooling required for your AI data center.

SambaNova enables inference providers to meet the insatiable demands of AI within your existing air-cooled data center.

How RDU Dataflow Architecture Works

Scale AI without sky-high costs

Service providers are pressured to serve more models, more tokens, and more AI applications than ever before. We all want fast AI inference, but we face limitations with existing infrastructure including model density per rack, power constraints, and scalability.

What if you could keep your current infrastructure and add energy-efficient racks to your data center — without enlarging your footprint? Not all racks and chips are designed the same. SambaNova builds for the future of AI.
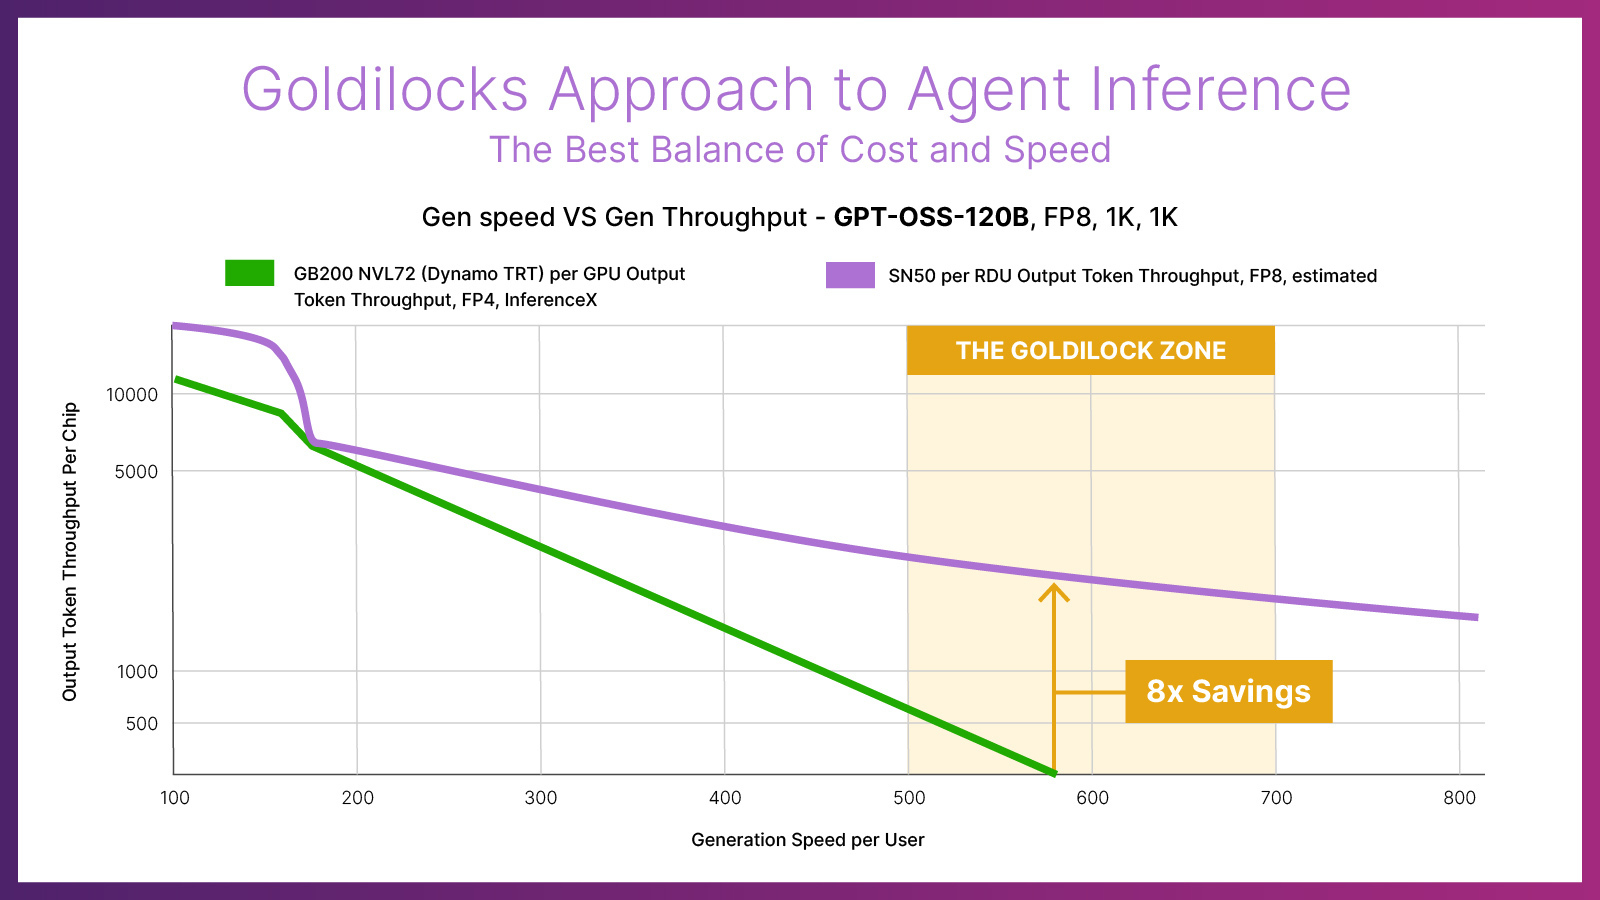
Chart - Gen speed VS Gen Throughput - GPT-OSS-120B - v4